Opus 5.5 on RoboDojo-RC Tier 1: higher scores at lower cost
September 23, 2026
We compare GPT-6 Astra, Opus 5.5, and Opus 5 on six adapted RoboDojo real-world tasks using I2RT YAM arms and Inspect Robots. We call this adaptation RoboDojo-RC Tier 1 to distinguish it from the original benchmark: we make small changes to the physical setups and instructions and use adapted progress rubrics. The task instructions and rubrics used in this evaluation are listed below.
We evaluated Astra on the 18 real-world RoboDojo tasks and selected the six easiest tasks with the highest scores as RoboDojo-RC Tier 1.
Opus 5.5 reaches similar average progress to Astra at 21% lower estimated cost with matched caching
Opus 5.5 averages 36.0% progress at $0.90 per trial, compared with Astra’s 36.7% at $1.14 (cache-adjusted estimate). Across 120 trials each, Astra fully completed 5 and Opus 5.5 completed 1.
Small dots show individual trials; labeled dots show model means. Horizontal and vertical bars show marginal 95% confidence intervals for mean cost and progress (20,000 bootstrap resamples within each task; cost assumptions held fixed). The arrow connects Opus 5 to Opus 5.5. All scores and token counts come from real robot trials. * Only Astra’s cost is adjusted: we calculate each recorded Astra trial’s cost assuming successful caching at matched markers, including cache-write charges. Original outputs are retained; no new responses were generated. Opus cost estimates use their recorded cache usage.
Astra reaches similar average progress with fewer output tokens
Astra averages 3,829 output tokens per trial; Opus 5.5 averages 14,496. Token counts alone do not determine cost: input usage and standard token prices differ between models.
Small translucent dots show individual trials; larger labeled dots show model means. The arrow connects the Opus 5 and Opus 5.5 means. The vertical axis spans 0–100% to include every trial. Output totals include reasoning tokens where reported by the provider.
Scoring
A human grader scored each trial using the task-specific rubric below. Scores range from 0 to 1 and are plotted as percentages; 1 means the full task was completed. Partial scores capture observable progress toward the task.
RoboDojo-RC Tier 1 tasks
Six tasks, with instructions, scoring rubrics, human demonstrations, and model trials.
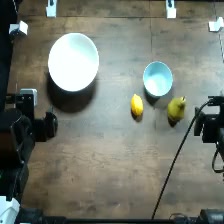
Pack And Pour Fruit
“Place all the fruits into the blue bowl, then pour the fruits from the blue bowl into the large white bowl.”
| Score | Observable milestone |
|---|---|
| 0 | No fruit successfully packed and no higher criterion achieved. |
| 0.1 | One fruit successfully placed into the small bowl. |
| 0.3 | Two fruits successfully contained in the small bowl at the same time. |
| 0.5 | Three fruits successfully contained in the small bowl at the same time. |
| 0.7 | Small bowl lifted clear of its supporting surface with all three fruits inside. |
| 0.8 | One fruit poured from the small bowl into the large bowl and remains there at trial end. |
| 0.9 | Two fruits poured from the small bowl into the large bowl and remain there at trial end. |
| 1 | All three fruits poured from the small bowl into the large bowl and remain there at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 17.0%; Opus 5.5: 24.0%; Opus 5: 17.0%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
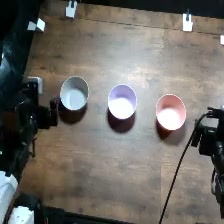
Stack Bowls
“Stack the bowls on the table.”
| Score | Observable milestone |
|---|---|
| 0 | No qualifying overlap or stack at trial end. |
| 0.25 | Two bowls overlapping at trial end. |
| 0.5 | Two bowls stacked at trial end. |
| 0.75 | Three bowls overlapping in one connected arrangement at trial end. |
| 1 | Three bowls stacked at trial end. |
GPT-6 Astra: 3/20 completed, 65.0% mean progress; Opus 5.5: 0/20 completed, 42.5% mean progress; Opus 5: 2/20 completed, 30.0% mean progress.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
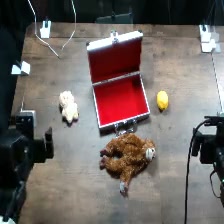
Store In Safe
“Place all the objects into the safe, then close the safe.”
| Score | Observable milestone |
|---|---|
| 0 | No objects inside the safe at trial end. |
| 0.25 | One object inside the safe at trial end. |
| 0.5 | Two objects inside the safe at trial end. |
| 0.75 | Three objects inside the safe at trial end. |
| 1 | Three objects inside the safe and the lid closed at trial end. |
GPT-6 Astra: 2/20 completed, 53.8% mean progress; Opus 5.5: 1/20 completed, 48.8% mean progress; Opus 5: 0/20 completed, 25.0% mean progress.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Cap Pen
“Pick up the pen and the pen cap, then put the cap on the pen.”
| Score | Observable milestone |
|---|---|
| 0 | Neither pen nor cap picked up. |
| 0.2 | Pen or cap picked up. |
| 0.5 | Pen and cap both held off the surface simultaneously. |
| 0.75 | Pen and cap touch while both are held in the air. No alignment requirement. |
| 1 | Cap successfully placed onto the pen and remains attached at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 41.0%; Opus 5.5: 57.0%; Opus 5: 20.5%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Stand Up Bottles
“Stand all three bottles upright.”
| Score | Observable milestone |
|---|---|
| 0 | No bottles upright and no bottle successfully gripped and lifted. |
| 0.1 | A bottle gripped and lifted clear of its supporting surface. |
| 0.4 | One bottle upright at trial end. |
| 0.7 | Two bottles upright at trial end. |
| 1 | Three bottles upright at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 2.5%; Opus 5.5: 0.5%; Opus 5: 5.0%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Sort Objects
“Classify the two types of objects on the table and place them into the two baskets.”
| Score per basket | Final contents |
|---|---|
| 0 | Empty, mixed categories, or only the category assigned to the other basket. |
| 0.17 | One object of its assigned category; no unrelated objects. |
| 0.33 | Two objects of its assigned category; no unrelated objects. |
| 0.5 | All three objects of its assigned category; no unrelated objects. |
Add the two basket scores. Assign a different category to each basket; either assignment is valid unless specified by the setup.
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 40.9%; Opus 5.5: 43.3%; Opus 5: 21.8%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Results
Across all six tasks
| Task | Model | Trials | Completed | Mean progress | Est. cost* | Mean input tokens | Mean output tokens |
|---|---|---|---|---|---|---|---|
| All six tasks | GPT-6 Astra | 120 | 5/120 | 36.7% | $1.14 | 330,361 | 3,829 |
| All six tasks | Opus 5.5 | 120 | 1/120 | 36.0% | $0.90 | 717,344 | 14,496 |
| All six tasks | Opus 5 | 120 | 2/120 | 19.9% | $1.76 | 920,821 | 23,308 |
120 trials per model, with 20 trials per task. Progress, estimated cost, and token counts are averages per trial; completed counts are totals across all six tasks.
By task
| Task | Model | Trials | Completed | Mean progress | Est. cost* | Mean input tokens | Mean output tokens |
|---|---|---|---|---|---|---|---|
| Pack And Pour Fruit | GPT-6 Astra | 20 | 0/20 | 17.0% | $1.08 | 318,946 | 3,264 |
| Pack And Pour Fruit | Opus 5.5 | 20 | 0/20 | 24.0% | $0.82 | 696,942 | 12,042 |
| Pack And Pour Fruit | Opus 5 | 20 | 0/20 | 17.0% | $1.66 | 925,100 | 20,197 |
| Stack Bowls | GPT-6 Astra | 20 | 3/20 | 65.0% | $1.09 | 311,199 | 3,698 |
| Stack Bowls | Opus 5.5 | 20 | 0/20 | 42.5% | $0.90 | 728,603 | 14,423 |
| Stack Bowls | Opus 5 | 20 | 2/20 | 30.0% | $1.98 | 1,006,014 | 27,476 |
| Store In Safe | GPT-6 Astra | 20 | 2/20 | 53.8% | $1.27 | 402,561 | 3,583 |
| Store In Safe | Opus 5.5 | 20 | 1/20 | 48.8% | $0.78 | 659,302 | 11,348 |
| Store In Safe | Opus 5 | 20 | 0/20 | 25.0% | $1.40 | 778,226 | 16,737 |
| Cap Pen | GPT-6 Astra | 20 | 0/20 | 41.0% | $1.13 | 307,986 | 4,324 |
| Cap Pen | Opus 5.5 | 20 | 0/20 | 57.0% | $1.02 | 720,587 | 18,645 |
| Cap Pen | Opus 5 | 20 | 0/20 | 20.5% | $1.83 | 891,918 | 25,996 |
| Stand Up Bottles | GPT-6 Astra | 20 | 0/20 | 2.5% | $1.03 | 269,480 | 4,138 |
| Stand Up Bottles | Opus 5.5 | 20 | 0/20 | 0.5% | $0.96 | 712,617 | 16,654 |
| Stand Up Bottles | Opus 5 | 20 | 0/20 | 5.0% | $2.09 | 1,039,856 | 30,067 |
| Sort Objects | GPT-6 Astra | 20 | 0/20 | 40.9% | $1.23 | 371,991 | 3,968 |
| Sort Objects | Opus 5.5 | 20 | 0/20 | 43.3% | $0.91 | 786,013 | 13,863 |
| Sort Objects | Opus 5 | 20 | 0/20 | 21.8% | $1.59 | 883,811 | 19,375 |
Every average in this table uses all 20 graded trials for that task and model.
* Scores and token counts are measured from real trials. Astra’s cost is calculated from each recorded conversation assuming successful caching at matched markers; Opus costs use recorded cache usage. Only the caching adjustment to Astra’s cost is modeled.
Trial CSV (uncached costs) · Task summaries (uncached costs)
All runs
360 trials · 60 per task · 20 per model. Open a task, then a model, to browse transcripts, camera videos, and run data.
Bars and counts: zero progress (light gray), partial progress (blue-gray), complete (teal). Progress is shown from 0 to 100. Trial numbers restart for each task and model.
Technical specifications
| Field | Value |
|---|---|
| Benchmark | RoboDojo-RC Tier 1: six adapted RoboDojo real-world tasks, each with its own progress rubric |
| Embodiment | Bimanual I2RT YAM arms with parallel-jaw grippers |
| Bill of materials | Download BOM (CSV) |
| Control | Absolute end-effector poses through the agent’s tools; recorded control frequency 10 Hz |
| Observation | Top, left-wrist, and right-wrist camera views plus robot state; recorded frames are 224 × 224 pixels |
| Policies | All three models use the Inspect Robots agent policy at medium effort, with a 40-model-call budget, 900-step cap, and 25% speed cap |
| Harness | Inspect Robots 0.58.0 |
| Trials | Trial counts are listed for each task and model in Results |
| Displayed costs | Costs use recorded token counts. For Astra, we apply matched cache markers to all 120 recorded conversations and count their input prefixes, assuming a cold cache per trial and successful reuse within 30 minutes. We preserve original outputs and apply Astra’s rates: $1 / $12.50 / $10 / $50 per million cache-read / cache-write / remaining-input / output tokens. Scores and token counts are unchanged. Downloads retain uncached costs, identified by cost_basis. |
Input / output prices per million tokens: Astra $10 / $50; Opus 5.5 $4 / $20; Opus 5 $5 / $25. Downloadable CSV and run-data costs use standard rates without caching; they exclude robot operation and are not invoice amounts. Sources: OpenAI pricing · Anthropic pricing.
Limitations
- Scores were assigned by human operators who knew the model, so grading is open to unconscious bias.
- We adapted the setups, instructions, embodiment, and rubrics. Scores are not directly comparable with the original RoboDojo benchmark.
- We reset the objects by hand and made our best effort to keep their placement consistent between trials. Some variation in placement may remain.
- Models were evaluated at medium effort only. The same effort setting does not guarantee the same reasoning budget across providers.
- Astra’s cache-adjusted cost assumes successful writes and reuse at the configured markers. Actual cache availability may differ; no new model responses were generated for this calculation. All performance results are from the actual trials. Caching differed across providers and can affect latency, so the video’s wall-clock comparison should be interpreted in that context.