GPT-6 Sol on RoboDojo-RC Tier 1
September 24, 2026
Following our Opus 5.5 report published yesterday, we compare GPT-6 Sol, GPT-5.6 Sol, and GPT-6 Astra on the same six RoboDojo-RC Tier 1 tasks.
We are keen to understand capabilities at the frontier, so we evaluate all three models at high reasoning effort, with Fast mode to reduce response latency.
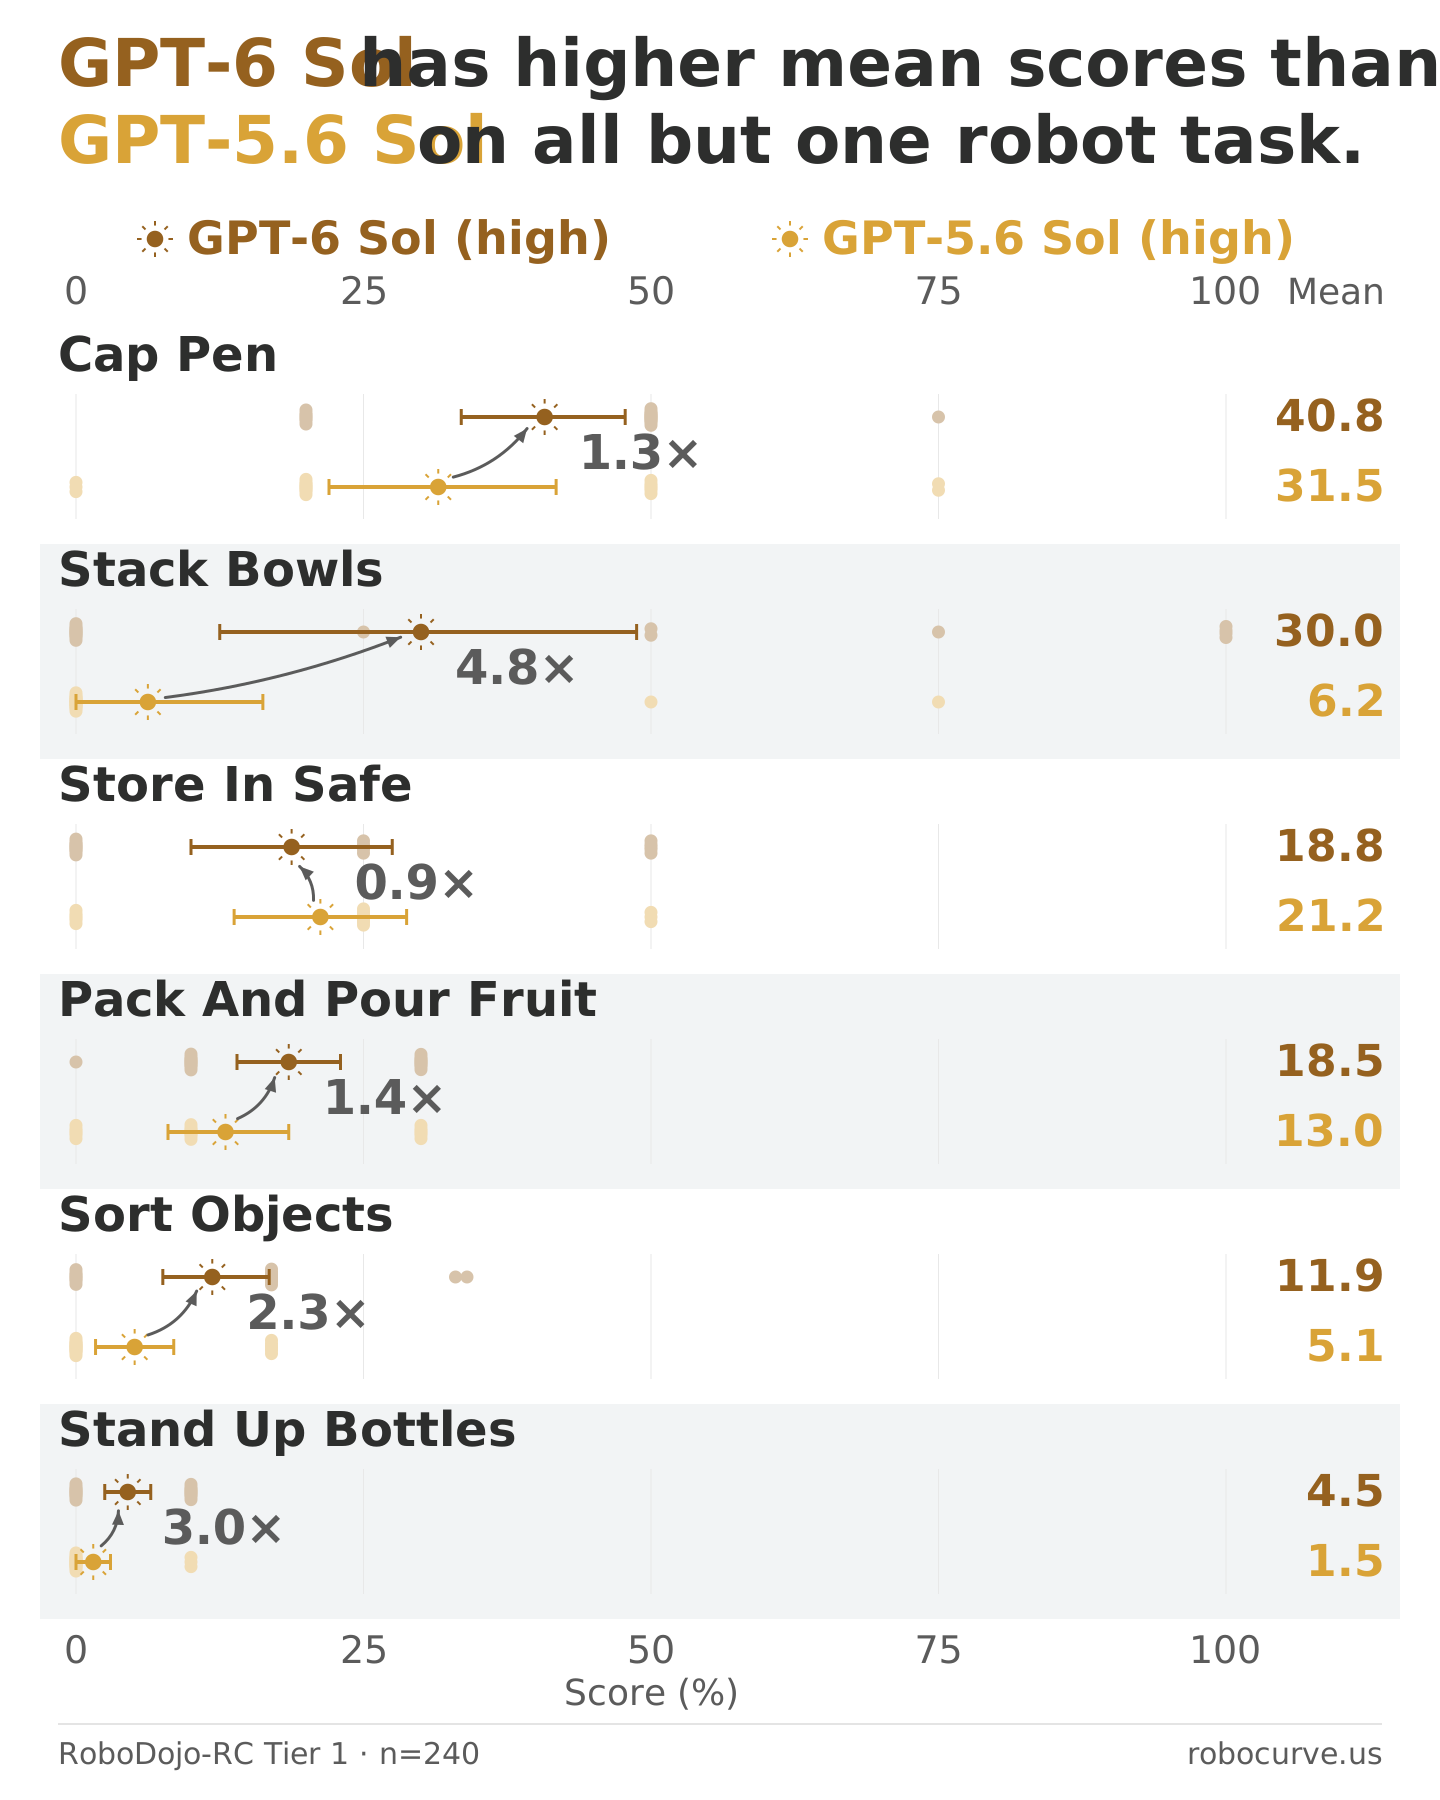
GPT-6 Sol has higher mean scores than GPT-5.6 Sol on all but one robot task.
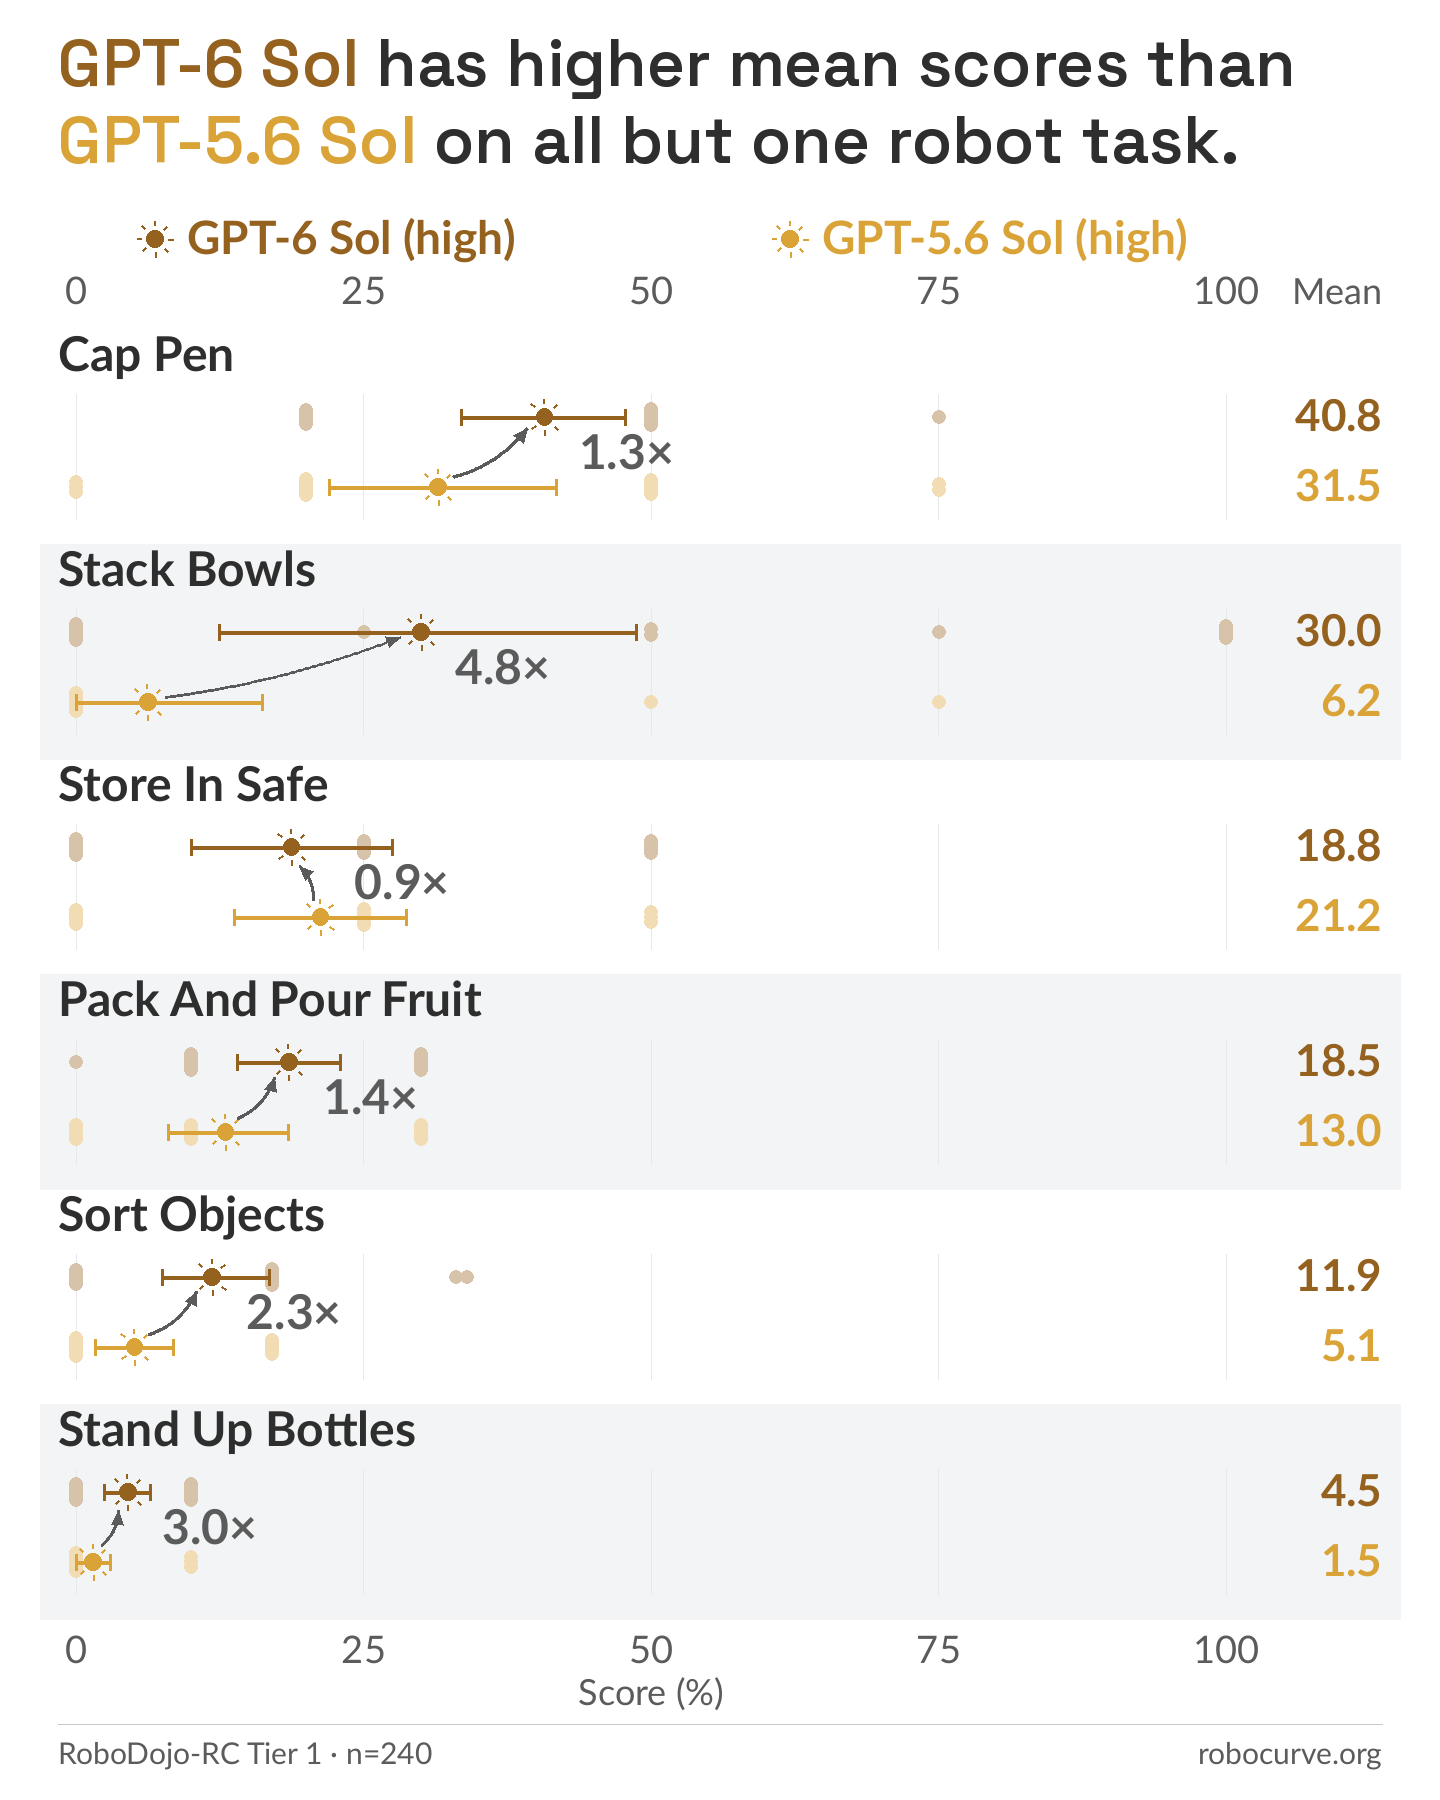
240 trials · 20 per model per task. Both models use high effort and Fast mode. Small dots show trials; sun markers show means; bars show 95% bootstrap confidence intervals. Arrows compare mean scores. Tasks are ordered by GPT-6 Sol’s mean score, highest first.
Download PNG · Download SVG · 1440 × 1800
GPT-6 Sol scores 1.6× as high as GPT-5.6 Sol at 53% of the cost
GPT-6 Sol averages 20.7% progress at $0.95 per trial, compared with GPT-5.6 Sol’s 13.1% at $1.77. Astra averages 38.8% at $3.38.
Small dots show individual trials; labeled dots show model means. The arrow connects GPT-5.6 Sol to GPT-6 Sol. Costs use recorded input, output, cache-read, and cache-write tokens at Fast-mode rates for all three models.
Progress and output tokens
Mean output tokens per trial: GPT-6 Sol 12,956; GPT-5.6 Sol 11,419; Astra 8,010.
Small dots show individual trials; labeled dots show model means. The arrow connects GPT-5.6 Sol to GPT-6 Sol. Output totals include reported reasoning tokens. The 0–100% axis includes every trial.
Progress and wall-clock time
Mean recorded trial duration: GPT-6 Sol 3.73 minutes; GPT-5.6 Sol 3.71 minutes; Astra 3.85 minutes.
Small dots show individual trials; labeled dots show model means. Wall-clock time is the recorded duration of each trial, including model responses and robot actions, rather than time to successful completion. All three models use high effort, Fast mode, and explicit caching; observed durations include any differences in cache performance and service latency.
Scoring
A human grader scored each trial using the task-specific rubric below. Scores range from 0 to 1 and are plotted as percentages; 1 means the full task was completed. Partial scores capture observable progress toward the task.
RoboDojo-RC Tier 1 tasks
Six tasks, with instructions, scoring rubrics, human demonstrations, and model trials.
Stack Bowls
“Stack the bowls on the table.”
| Score | Observable milestone |
|---|---|
| 0 | No qualifying overlap or stack at trial end. |
| 0.25 | Two bowls overlapping at trial end. |
| 0.5 | Two bowls stacked at trial end. |
| 0.75 | Three bowls overlapping in one connected arrangement at trial end. |
| 1 | Three bowls stacked at trial end. |
GPT-6 Astra: 20.0% completed, 68.8% mean progress; GPT-6 Sol: 20.0% completed, 30.0% mean progress; GPT-5.6 Sol: 0.0% completed, 6.2% mean progress.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Store In Safe
“Place all the objects into the safe, then close the safe.”
| Score | Observable milestone |
|---|---|
| 0 | No objects inside the safe at trial end. |
| 0.25 | One object inside the safe at trial end. |
| 0.5 | Two objects inside the safe at trial end. |
| 0.75 | Three objects inside the safe at trial end. |
| 1 | Three objects inside the safe and the lid closed at trial end. |
GPT-6 Astra: 5.0% completed, 47.5% mean progress; GPT-6 Sol: 0.0% completed, 18.8% mean progress; GPT-5.6 Sol: 0.0% completed, 21.2% mean progress.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Sort Objects
“Classify the two types of objects on the table and place them into the two baskets.”
| Score per basket | Final contents |
|---|---|
| 0 | Empty, mixed categories, or only the category assigned to the other basket. |
| 0.17 | One object of its assigned category; no unrelated objects. |
| 0.33 | Two objects of its assigned category; no unrelated objects. |
| 0.5 | All three objects of its assigned category; no unrelated objects. |
Add the two basket scores. Assign a different category to each basket; either assignment is valid unless specified by the setup.
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 47.5%; GPT-6 Sol: 11.9%; GPT-5.6 Sol: 5.1%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Cap Pen
“Pick up the pen and the pen cap, then put the cap on the pen.”
| Score | Observable milestone |
|---|---|
| 0 | Neither pen nor cap picked up. |
| 0.2 | Pen or cap picked up. |
| 0.5 | Pen and cap both held off the surface simultaneously. |
| 0.75 | Pen and cap touch while both are held in the air. No alignment requirement. |
| 1 | Cap successfully placed onto the pen and remains attached at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 39.8%; GPT-6 Sol: 40.8%; GPT-5.6 Sol: 31.5%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Pack And Pour Fruit
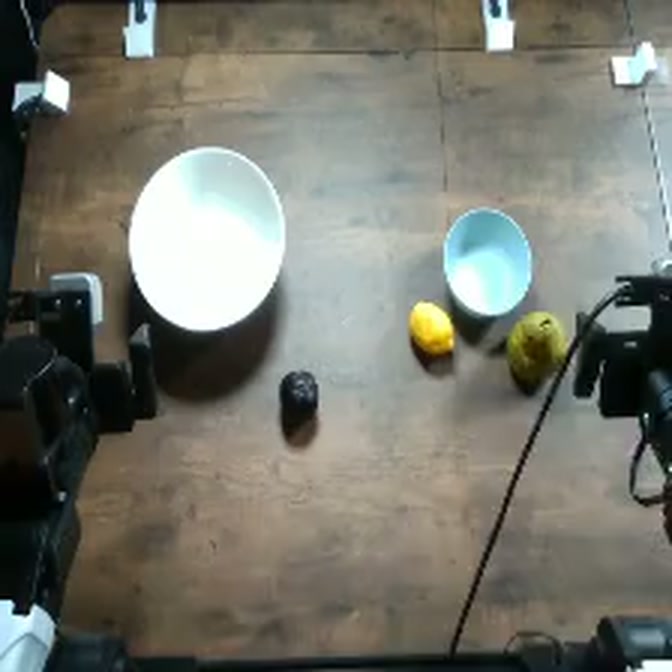
“Place all the fruits into the blue bowl, then pour the fruits from the blue bowl into the large white bowl.”
| Score | Observable milestone |
|---|---|
| 0 | No fruit successfully packed and no higher criterion achieved. |
| 0.1 | One fruit successfully placed into the small bowl. |
| 0.3 | Two fruits successfully contained in the small bowl at the same time. |
| 0.5 | Three fruits successfully contained in the small bowl at the same time. |
| 0.7 | Small bowl lifted clear of its supporting surface with all three fruits inside. |
| 0.8 | One fruit poured from the small bowl into the large bowl and remains there at trial end. |
| 0.9 | Two fruits poured from the small bowl into the large bowl and remain there at trial end. |
| 1 | All three fruits poured from the small bowl into the large bowl and remain there at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 29.0%; GPT-6 Sol: 18.5%; GPT-5.6 Sol: 13.0%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Stand Up Bottles
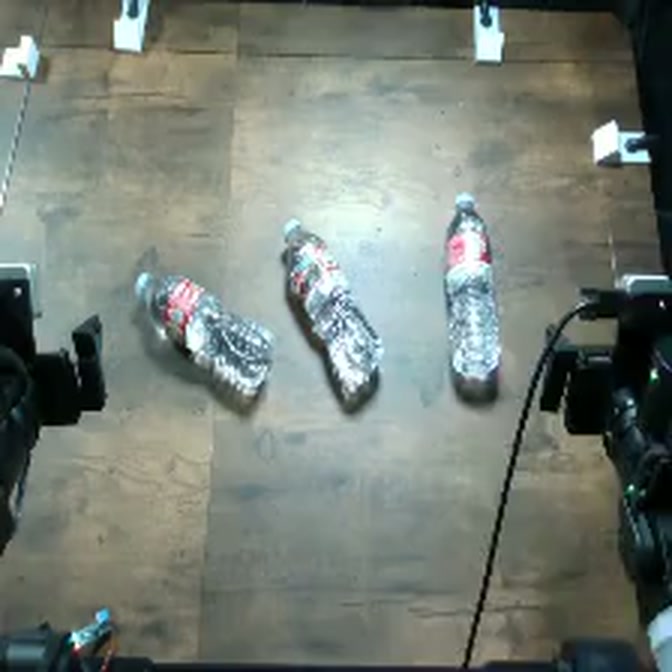
“Stand all three bottles upright.”
| Score | Observable milestone |
|---|---|
| 0 | No bottles upright and no bottle successfully gripped and lifted. |
| 0.1 | A bottle gripped and lifted clear of its supporting surface. |
| 0.4 | One bottle upright at trial end. |
| 0.7 | Two bottles upright at trial end. |
| 1 | Three bottles upright at trial end. |
No model completed this task in the graded trials. Mean progress: GPT-6 Astra: 0.5%; GPT-6 Sol: 4.5%; GPT-5.6 Sol: 1.5%.
Representative runs
Trial progress
Individual progress scores, diamond means, and approximate 95% t intervals clipped to 0–100%.
Results
720 trials across six model and effort configurations, with 120 trials per configuration and 20 per task.
Across all six tasks
| Task | Model | Trials | Completed | Mean score | Est. cost | Mean input tokens | Mean output tokens |
|---|---|---|---|---|---|---|---|
| All six tasks | GPT-6 Astra (high) | 120 | 5/120 | 38.8% | $3.38 | 487,410 | 8,010 |
| All six tasks | GPT-6 Sol (high) | 120 | 4/120 | 20.7% | $0.95 | 674,670 | 12,956 |
| All six tasks | GPT-5.6 Sol (high) | 120 | 0/120 | 13.1% | $1.77 | 652,060 | 11,419 |
| All six tasks | GPT-6 Astra (medium) | 120 | 5/120 | 36.7% | $1.14 | 330,361 | 3,829 |
| All six tasks | Opus 5.5 (medium) | 120 | 1/120 | 36.0% | $0.90 | 717,344 | 14,496 |
| All six tasks | Opus 5 (medium) | 120 | 2/120 | 19.9% | $1.76 | 920,821 | 23,308 |
Trial and completion counts are totals. Means weight the six tasks equally.
By task
| Task | Model | Completed | Mean score | Est. cost | Mean input tokens | Mean output tokens |
|---|---|---|---|---|---|---|
| Stack Bowls | GPT-6 Astra (high) | 4/20 | 68.8% | $3.21 | 460,150 | 7,571 |
| Stack Bowls | GPT-6 Sol (high) | 4/20 | 30.0% | $0.94 | 652,544 | 13,387 |
| Stack Bowls | GPT-5.6 Sol (high) | 0/20 | 6.2% | $1.82 | 658,974 | 12,226 |
| Stack Bowls | GPT-6 Astra (medium) | 3/20 | 65.0% | $1.09 | 311,199 | 3,698 |
| Stack Bowls | Opus 5.5 (medium) | 0/20 | 42.5% | $0.90 | 728,603 | 14,423 |
| Stack Bowls | Opus 5 (medium) | 2/20 | 30.0% | $1.98 | 1,006,014 | 27,476 |
| Store In Safe | GPT-6 Astra (high) | 1/20 | 47.5% | $3.31 | 497,476 | 7,148 |
| Store In Safe | GPT-6 Sol (high) | 0/20 | 18.8% | $0.88 | 641,416 | 11,457 |
| Store In Safe | GPT-5.6 Sol (high) | 0/20 | 21.2% | $1.69 | 640,728 | 10,181 |
| Store In Safe | GPT-6 Astra (medium) | 2/20 | 53.8% | $1.27 | 402,561 | 3,583 |
| Store In Safe | Opus 5.5 (medium) | 1/20 | 48.8% | $0.78 | 659,302 | 11,348 |
| Store In Safe | Opus 5 (medium) | 0/20 | 25.0% | $1.40 | 778,226 | 16,737 |
| Sort Objects | GPT-6 Astra (high) | 0/20 | 47.5% | $3.65 | 540,543 | 8,615 |
| Sort Objects | GPT-6 Sol (high) | 0/20 | 11.9% | $0.92 | 673,865 | 12,195 |
| Sort Objects | GPT-5.6 Sol (high) | 0/20 | 5.1% | $1.71 | 640,381 | 10,580 |
| Sort Objects | GPT-6 Astra (medium) | 0/20 | 40.9% | $1.23 | 371,991 | 3,968 |
| Sort Objects | Opus 5.5 (medium) | 0/20 | 43.3% | $0.91 | 786,013 | 13,863 |
| Sort Objects | Opus 5 (medium) | 0/20 | 21.8% | $1.59 | 883,811 | 19,375 |
| Cap Pen | GPT-6 Astra (high) | 0/20 | 39.8% | $3.80 | 537,892 | 9,643 |
| Cap Pen | GPT-6 Sol (high) | 0/20 | 40.8% | $1.11 | 762,016 | 16,604 |
| Cap Pen | GPT-5.6 Sol (high) | 0/20 | 31.5% | $1.93 | 685,615 | 13,399 |
| Cap Pen | GPT-6 Astra (medium) | 0/20 | 41.0% | $1.13 | 307,986 | 4,324 |
| Cap Pen | Opus 5.5 (medium) | 0/20 | 57.0% | $1.02 | 720,587 | 18,645 |
| Cap Pen | Opus 5 (medium) | 0/20 | 20.5% | $1.83 | 891,918 | 25,996 |
| Pack And Pour Fruit | GPT-6 Astra (high) | 0/20 | 29.0% | $3.23 | 484,532 | 6,846 |
| Pack And Pour Fruit | GPT-6 Sol (high) | 0/20 | 18.5% | $0.87 | 639,819 | 11,065 |
| Pack And Pour Fruit | GPT-5.6 Sol (high) | 0/20 | 13.0% | $1.61 | 606,184 | 9,552 |
| Pack And Pour Fruit | GPT-6 Astra (medium) | 0/20 | 17.0% | $1.08 | 318,946 | 3,264 |
| Pack And Pour Fruit | Opus 5.5 (medium) | 0/20 | 24.0% | $0.82 | 696,942 | 12,042 |
| Pack And Pour Fruit | Opus 5 (medium) | 0/20 | 17.0% | $1.66 | 925,100 | 20,197 |
| Stand Up Bottles | GPT-6 Astra (high) | 0/20 | 0.5% | $3.09 | 403,867 | 8,239 |
| Stand Up Bottles | GPT-6 Sol (high) | 0/20 | 4.5% | $0.95 | 678,363 | 13,028 |
| Stand Up Bottles | GPT-5.6 Sol (high) | 0/20 | 1.5% | $1.86 | 680,476 | 12,579 |
| Stand Up Bottles | GPT-6 Astra (medium) | 0/20 | 2.5% | $1.03 | 269,480 | 4,138 |
| Stand Up Bottles | Opus 5.5 (medium) | 0/20 | 0.5% | $0.96 | 712,617 | 16,654 |
| Stand Up Bottles | Opus 5 (medium) | 0/20 | 5.0% | $2.09 | 1,039,856 | 30,067 |
High-effort configurations use Fast mode; medium-effort configurations use standard mode. Astra (medium) uses the earlier report’s matched-cache cost estimate; other configurations use recorded cache usage.
All 720 trials (CSV) · Task summaries (CSV)
All runs
720 graded trials across six tasks. Open a task and model/effort group to browse transcripts, camera videos, and downloadable run data.
Bars and counts: zero progress (light gray), partial progress (blue-gray), complete (teal). Progress is shown from 0 to 100. Trial numbers restart for each task and model.
Technical specifications
| Field | Value |
|---|---|
| Benchmark | RoboDojo-RC Tier 1: six adapted RoboDojo real-world tasks, each with its own progress rubric |
| Embodiment | Bimanual I2RT YAM arms with parallel-jaw grippers |
| Bill of materials | Download BOM (CSV) |
| Control | Absolute end-effector poses through the agent’s tools; recorded control frequency 10 Hz |
| Observation | Top, left-wrist, and right-wrist camera views plus robot state; recorded frames are 224 × 224 pixels |
| Policies | All three models use the Inspect Robots agent policy at high effort and Fast mode, with a 40-model-call budget, 900-step cap, and 25% speed cap |
| Harness | Inspect Robots |
| Trials | Trial counts are listed for each task and model in Results |
| Caching | Explicit caching is confirmed in the captured requests for every included trial. Displayed costs use the recorded cache counters, with no modeled cache-success adjustment. |
Fast-mode prices per million ordinary input / cache read / cache write / output tokens: Astra $20 / $2 / $25 / $100; GPT-6 Sol $4 / $0.40 / $5 / $20; GPT-5.6 Sol $8 / $0.80 / $10 / $40. All audited requests fall below the long-context pricing threshold. Source: OpenAI pricing.
Limitations
- Scores were assigned by human operators who knew the model, so grading is open to unconscious bias.
- We adapted the setups, instructions, embodiment, and rubrics. Scores are not directly comparable with the original RoboDojo benchmark.
- We reset the objects by hand and made our best effort to keep their placement consistent between trials. Some variation in placement may remain.
- Models were evaluated at high effort and Fast mode. The same effort setting does not guarantee equal reasoning-token budgets across models.
- Costs are based on recorded usage and published prices, not invoices. Video clips show selected examples and do not summarize the full score distribution.