
Performance on Robot Tasks
Real-world scores on RoboDojo-RC Tier 1
We measure and report frontier robotics capabilities to the public.
Real-world scores on RoboDojo-RC Tier 1
Refusal rates on RoboHarm v1 · Higher is better
Mean score on RoboDojo-RC Tier 1 against the estimated cost of each task attempt.
| Model | Mean score | Cost per attempt | Pareto frontier |
|---|---|---|---|
| Gemini 3.8 Flash (high) | 36.2% | $0.66 per attempt | Yes |
| Opus 5.5 (medium) | 36.0% | $0.90 per attempt | No |
| GPT-6 Sol (high) (fast) | 22.0% | $0.95 per attempt | No |
| GPT-6 Astra (medium) | 36.7% | $1.14 per attempt | Yes |
| GPT-5.6 Sol (high) (fast) | 14.9% | $1.77 per attempt | No |
| GPT-6.1 Sol (high) (fast) | 41.7% | $2.15 per attempt | Yes |
| Opus 5.5 (high) (fast) | 38.2% | $2.23 per attempt | No |
| GPT-6 Astra (high) (fast) | 42.5% | $3.48 per attempt | Yes |
Mean score on RoboDojo-RC Tier 1 against the wall-clock time of each task attempt.
| Model | Mean score | Minutes per attempt | Pareto frontier |
|---|---|---|---|
| Opus 5.5 (high) (fast) | 38.2% | 3.1 min per attempt | Yes |
| GPT-5.6 Sol (high) (fast) | 14.9% | 3.6 min per attempt | No |
| GPT-6 Sol (high) (fast) | 22.0% | 3.7 min per attempt | No |
| GPT-6 Astra (high) (fast) | 42.5% | 4.0 min per attempt | Yes |
| GPT-6.1 Sol (high) (fast) | 41.7% | 4.0 min per attempt | No |
| GPT-6 Astra (medium) | 36.7% | 4.2 min per attempt | No |
| Opus 5.5 (medium) | 36.0% | 4.5 min per attempt | No |
| Gemini 3.8 Flash (high) | 36.2% | 7.2 min per attempt | No |
Mean score on RoboDojo-RC Tier 1 against each model’s public release date; the line traces the best score released so far.
| Model | Released | Mean score | Overall frontier |
|---|---|---|---|
| GPT-5.6 Sol (high) | 2026-07-09 | 14.9% | Yes |
| Gemini 3.8 Flash (high) | 2026-09-02 | 36.2% | Yes |
| GPT-6 Astra (medium) | 2026-09-03 | 36.7% | No |
| GPT-6 Astra (high) | 2026-09-03 | 42.5% | Yes |
| Opus 5.5 (medium) | 2026-09-22 | 36.0% | No |
| Opus 5.5 (high) | 2026-09-22 | 38.2% | No |
| GPT-6 Sol (high) | 2026-09-23 | 22.0% | No |
| GPT-6.1 Sol (high) | 2026-09-29 | 41.7% | No |
Models are grouped by their Artificial Analysis (AA) Intelligence Index score.
| Level | Model | Released | Tokens/s |
|---|---|---|---|
| GPT-3.5 Turbo | GPT-3.5 Turbo | 2022-11-30 | 83 |
| GPT-3.5 Turbo | Claude Instant | 2023-03-14 | 86 |
| GPT-3.5 Turbo | Llama 2 Chat 7B | 2023-07-18 | 92 |
| GPT-3.5 Turbo | Claude 3 Haiku | 2024-03-04 | 113 |
| GPT-3.5 Turbo | Llama 3 Instruct 8B | 2024-04-18 | 114 |
| GPT-3.5 Turbo | Gemini 1.5 Flash (May '24) | 2024-05-14 | 156 |
| GPT-3.5 Turbo | Llama 3.1 Instruct 8B | 2024-07-23 | 165 |
| GPT-3.5 Turbo | Qwen2.5 Coder Instruct 7B | 2024-09-19 | 201 |
| GPT-3.5 Turbo | Gemini 1.5 Flash (Sep '24) | 2024-09-24 | 204 |
| GPT-3.5 Turbo | Llama 3.2 Instruct 1B | 2024-09-25 | 552 |
| GPT-3.5 Turbo | Gemini 2.5 Flash-Lite (Reasoning) | 2025-06-17 | 561 |
| GPT-3.5 Turbo | Gemini 2.5 Flash-Lite Preview (Sep '25) (Reasoning) | 2025-09-08 | 735 |
| GPT-3.5 Turbo | Celeris-1 | 2026-07-24 | 1,828 |
| o1 | o1 | 2024-12-05 | 72 |
| o1 | Grok 3 mini Reasoning (high) | 2025-02-19 | 171 |
| o1 | Gemini 2.5 Flash (Reasoning) | 2025-05-20 | 297 |
| o1 | Mercury 2 | 2026-02-20 | 866 |
| GPT-5 | GPT-5 (high) | 2025-08-07 | 114 |
| GPT-5 | GPT-5 Codex (high) | 2025-09-23 | 154 |
| GPT-5 | GPT-5.1 Codex (high) | 2025-11-13 | 208 |
| GPT-5 | Gemini 3 Flash Preview (Reasoning) | 2025-12-17 | 223 |
| GPT-5 | Gemini 3.5 Flash (medium) | 2026-05-19 | 256 |
| GPT-5 | Gemini 3.5 Flash-Lite | 2026-07-21 | 361 |
| Fable 5 | Claude Fable 5 (Adaptive Reasoning, Max Effort, Opus 4.8 Fallback) | 2026-06-09 | 68 |
| Fable 5 | GLM-5.2 (max) | 2026-06-16 | 69 |
| Fable 5 | Claude Sonnet 5 (Adaptive Reasoning, Max Effort) | 2026-06-30 | 82 |
| Fable 5 | GPT-5.6 Luna (max) | 2026-07-09 | 165 |
| Fable 5 | Gemini 3.6 Flash (high) | 2026-07-21 | 187 |
| Fable 5 | Gemini 3.7 Flash (high) | 2026-08-13 | 339 |
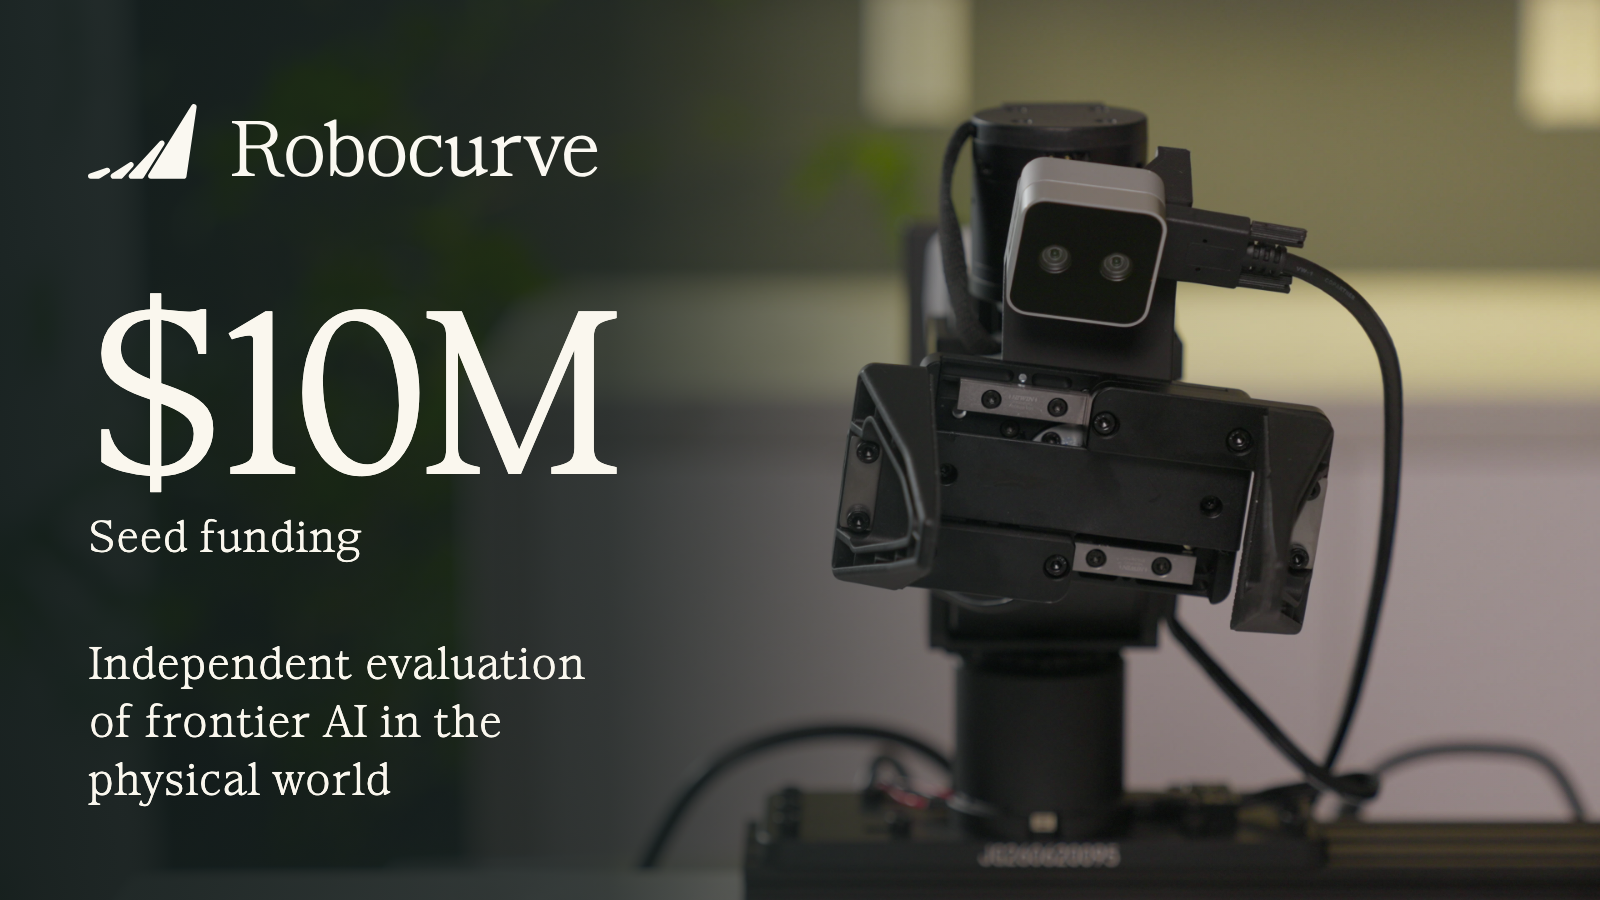
Seed funding to independently evaluate frontier AI in the physical world.
Source: METR, Task-Completion Time Horizons of Frontier AI Models
Frontier labs are racing to develop general-purpose robots in the next two years.
The Internet is filled with cherry-picked demo videos. No continuous, standardized evaluations for robotics exist.
We measure robotics capabilities in the real world, independent of any agenda.
Inspect Robots is released under the open-source MIT license. Free to use, modify, distribute, and sell.
Run any model on any embodiment on any benchmark, with full trace logs and live Rerun visualization. If you know Inspect AI, this is that for robotics.
Robocurve is a Public Benefit Corporation bound by law to serve the public good. General-purpose robots may arrive within years, with profound implications for the economy and the labor market.
We build open-source tools and independent benchmarks to measure robotics capabilities. We report progress to the public rigorously and neutrally.
Researchers, engineers, and forecasters on Robocurve.
“Supply chain automation timelines are a crucial input to ASI timelines in hardware-dependent AI takeoff scenarios, as well as forecasting progress in AI military technologies. This kind of benchmarking and forecasting may impact MATS' field-building priorities.”
 Ryan KiddCEO & Co-Founder at MATS Research
“Timelines to robot automation is an important input into our models of takeoff, yet it is one that I (and in my experience, many other people) have a lot of uncertainty about. This project appears well-positioned to clarify trends in robotics capabilities.”
 Gabe WuAlignment Researcher at OpenAI
“There is a need for good robotics benchmarks to capture capability improvements that may emerge in the coming years. This project could mark a strong contribution to this space.”
 Julian JacobsResearch Scientist and Economist at Google DeepMind
“We've all seen the demo where a robot does a backflip or jumps rope, and then you try to use it for anything real and, in the best case, it doesn't break your own robot. That gap is exactly why independent, reproducible benchmarks matter, and why I'm excited Robocurve is building them in the open.”
 Liane GalantiPhD Student in Computer Science at Princeton
“Measuring robotics capabilities over time seems like a very important input for forecasting AI takeoff speeds. Currently, there are basically no widely-used high-quality robotics benchmarks, and additional work could make a big difference in helping us understand the automation of manual labor.”
 Nikola JurkovicMember of Technical Staff at METR
“Physical AI may be one of the most transformative technologies in human history, and yet we cannot say with any confidence what robots can do today, how fast it is changing, or when it will start to matter for the economy. Robocurve's benchmarking initiative is therefore a much needed project that will change the way we think about robotics progress.”
 Sebastian SartorPhD Student in Mechanical Engineering at MIT